Drupal AI chatbot for existing Drupal websites
Your Drupal site controls which content is valid, who may see it, and which revision is published. A connected chatbot has to follow the same rules.
Start with selected content and real Drupal access scenarios.
A Drupal chatbot has to understand more than page text

Drupal content is structured
The information shown on one page may come from nodes, Paragraphs, taxonomy terms, media, files, referenced entities, and custom fields. The connector must preserve that structure well enough to retrieve the right passage and cite the right page.

Drupal access is contextual
Roles, groups, subscriptions, ownership, custom grants, and external identity systems can change what each person may see. Those rules must filter candidate sources before their text reaches the language model.

Drupal content keeps changing
Editors create revisions, publish translations, replace files, unpublish pages, and delete entities. The index needs to add, update, and remove records as these events happen.
What Drupal AI chatbot integration must respect
Before we connect retrieval, we align on the Drupal boundary: which entities feed the index, how access is evaluated, and which events keep records current.
- Content types, Paragraph types, fields, media, files, taxonomy, and languages in scope
- Roles, groups, subscriptions, custom grants, and identity context for retrieval
- Save, publish, translation, access change, file replacement, unpublish, and delete events

Content scope
We identify the content types, bundles, Paragraph types, fields, media, files, taxonomy, and referenced entities that may support an answer. Drafts and administrative fields stay outside the scope unless the agreed use case requires them.

Content representation
We decide how to turn structured Drupal data into searchable records. Each record can retain the entity ID, canonical URL, title, section, content type, language, revision, and other metadata needed for retrieval and citations.

Access model
We document anonymous access, authenticated roles, groups, subscriptions, custom grants, and any identity or entitlement service involved in the decision. Missing access data results in no restricted context being returned.

Change events
We map what should happen after a save, publication, new translation, changed access grant, file replacement, unpublish action, or deletion. A reconciliation job can detect records missed by the event-driven update path.
How Drupal content becomes a cited answer
Choose the integration path for your Drupal stack
We select the path after reviewing the current Drupal architecture and the first content collection.

Extend the current search setup
A site already using Drupal Search API, Solr, Elasticsearch, or another suitable index may reuse parts of that setup. We review its fields, access filters, language handling, update latency, and support for the retrieval metadata the chatbot needs.

Add a Drupal-specific connector
A custom connector can handle nested Paragraphs, custom entities, external files, non-standard publication rules, or fine-grained access logic. It gives the integration an explicit contract for additions, updates, removals, and citations.

Use a separate retrieval service
Drupal can remain the source of content and access decisions while another service handles chunking, embeddings, ranking, and model calls. The boundary must define data ownership, credentials, logs, failure handling, and the final access check.

After the architecture review
We select the path after reviewing the current Drupal architecture and the first content collection.
What a Drupal chatbot pilot will prove
Before a wider release, the pilot should confirm indexing, sync, access, and citations on real Drupal content and users.
The connector reads the intended content. The pilot indexes an agreed set of content types, fields, files, languages, and references. Sample records show which Drupal source produced each searchable passage.
Editorial changes reach the index
Editors expect answers to match what they just published. The pilot runs controlled Drupal changes and checks that the search index follows each event.
Editorial changes reach the index. Tests cover a new entity, an edited field, a new revision, a translation, an unpublished page, a deleted item, and a replaced file. Each step should add, update, or remove the matching retrieval record within the agreed time window.
Access rules hold during retrieval
The same question should not expose restricted Drupal content to every user. The pilot tests retrieval under several authenticated and anonymous contexts.
Access rules hold during retrieval. Test users with different roles, groups, subscriptions, or grants ask the same questions. The results show whether each user receives only the sources available in their Drupal session and whether cited links stay protected when opened.

Answers point back to Drupal
Users should see which Drupal pages or files grounded each answer. The pilot connects the chatbot output to live destinations your team can open and verify.
Answers point back to Drupal. A fixed question set checks cited URLs, unsupported statements, no-answer behavior, response time, and retrieval failures. The review produces a list of fixes required before a wider release.
Scope a focused Drupal chatbot pilot
Send the Drupal URL, the audiences who should use the chatbot, and the content collections that should ground answers. We will define the connector scope and the acceptance tests for a pilot on real access scenarios.
Start with one content scope, several user roles, and citations you can verify in Drupal.
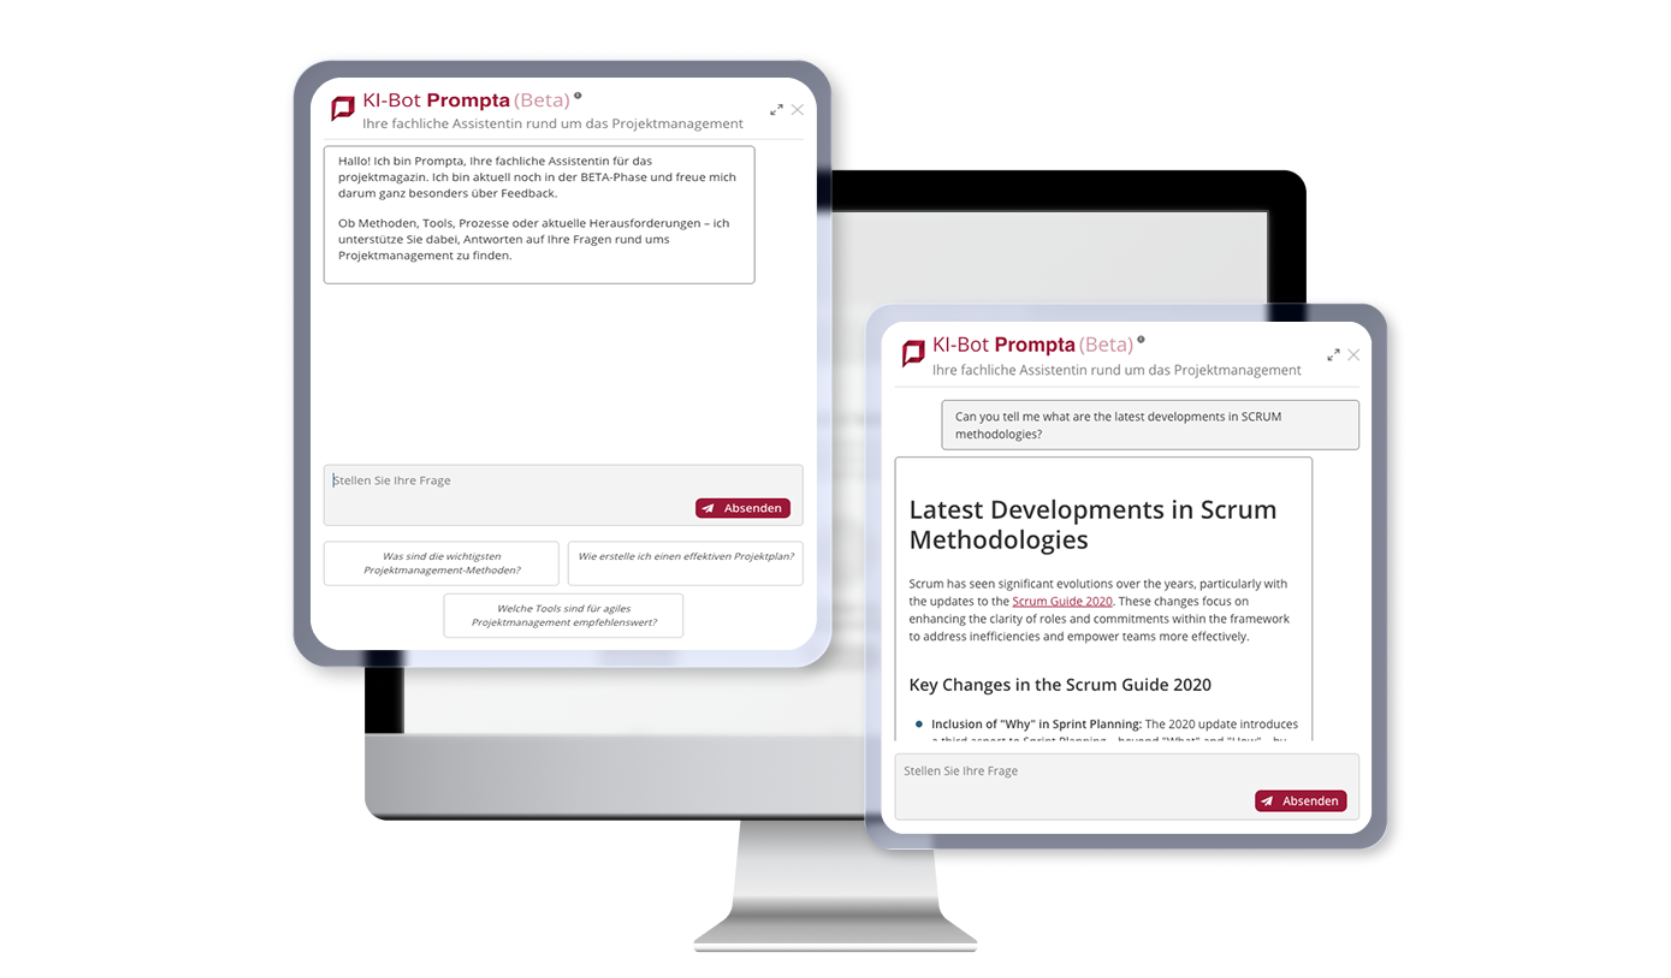
ProjektMagazin: Drupal content connected to a document chatbot
ProjektMagazin runs a Drupal knowledge platform containing articles, documents, templates, and methods. We connected its chatbot through JSON APIs and preserved metadata needed for retrieval and source attribution.
Drupal updates trigger re-indexing through webhooks, while scheduled synchronization catches missed changes. The system routes questions, cites source material, records feedback, and provides operating data for later adjustments.
Do you need a different Drupal AI service?
This page covers chatbot integration with an existing Drupal site. Use one of these routes when your main problem sits elsewhere.
Do not use this page for a generic chatbot offer outside your Drupal content model.

When this page is not the right fit
If you need a generic chatbot product outside your Drupal content model, start from the AI development for Drupal hub and pick the path that matches your platform.

Editorial content automation in Drupal
If the priority is Word and PDF imports, translations, metadata, or alt text inside editorial workflows, see Drupal AI automation for content teams.

Generative engine optimization for Drupal
If the goal is to improve how answer engines cite your public Drupal pages, see generative engine optimization services for Drupal.

Compare all Drupal AI paths
For an overview of automation, chatbot integration, and GEO on one Drupal platform, see AI development for Drupal.
Frequently asked questions about Drupal chatbot integration
Usually, yes. We first review the Drupal version, content model, custom entities, files, APIs, search stack, authentication, access logic, and hosting. This review shows which existing components can stay and where the site needs a connector or configuration change.
It depends on the content model and access requirements. Existing modules may cover the interface, provider connection, or basic search. Sites with nested Paragraphs, custom entities, subscriptions, external files, or custom grants often need additional mapping and synchronization logic.
It may reuse the current index or selected parts of the search pipeline. We check whether it contains the required fields, updates quickly enough, supports language and access filters, and can return source metadata suitable for citations.
The update path must remove the corresponding retrieval records. Event-driven removal handles normal changes, while reconciliation compares the index with current Drupal state and catches missed or failed operations.
Retrieval filters use the approved identity, role, group, subscription, or grant context before any passage reaches the model. A cited link remains protected by Drupal’s own access check. The pilot tests several users and recent permission changes.
Yes, if the connector preserves each language variant and its publication state. Retrieval can filter or rank by the user’s language, while citations point to the matching Drupal translation. The pilot should also test missing and fallback translations.